01 — Problem
The source data is aggregated frequency counts of name tokens per country — roughly 12.4M forename rows and 21.1M surname rows — with no full-name records anywhere in it. Training a classifier that takes 'First Last' at inference therefore needs full names that do not exist in the input, and the task itself is genuinely ambiguous: 'ali ali' legitimately appears in 30 of the 104 countries.
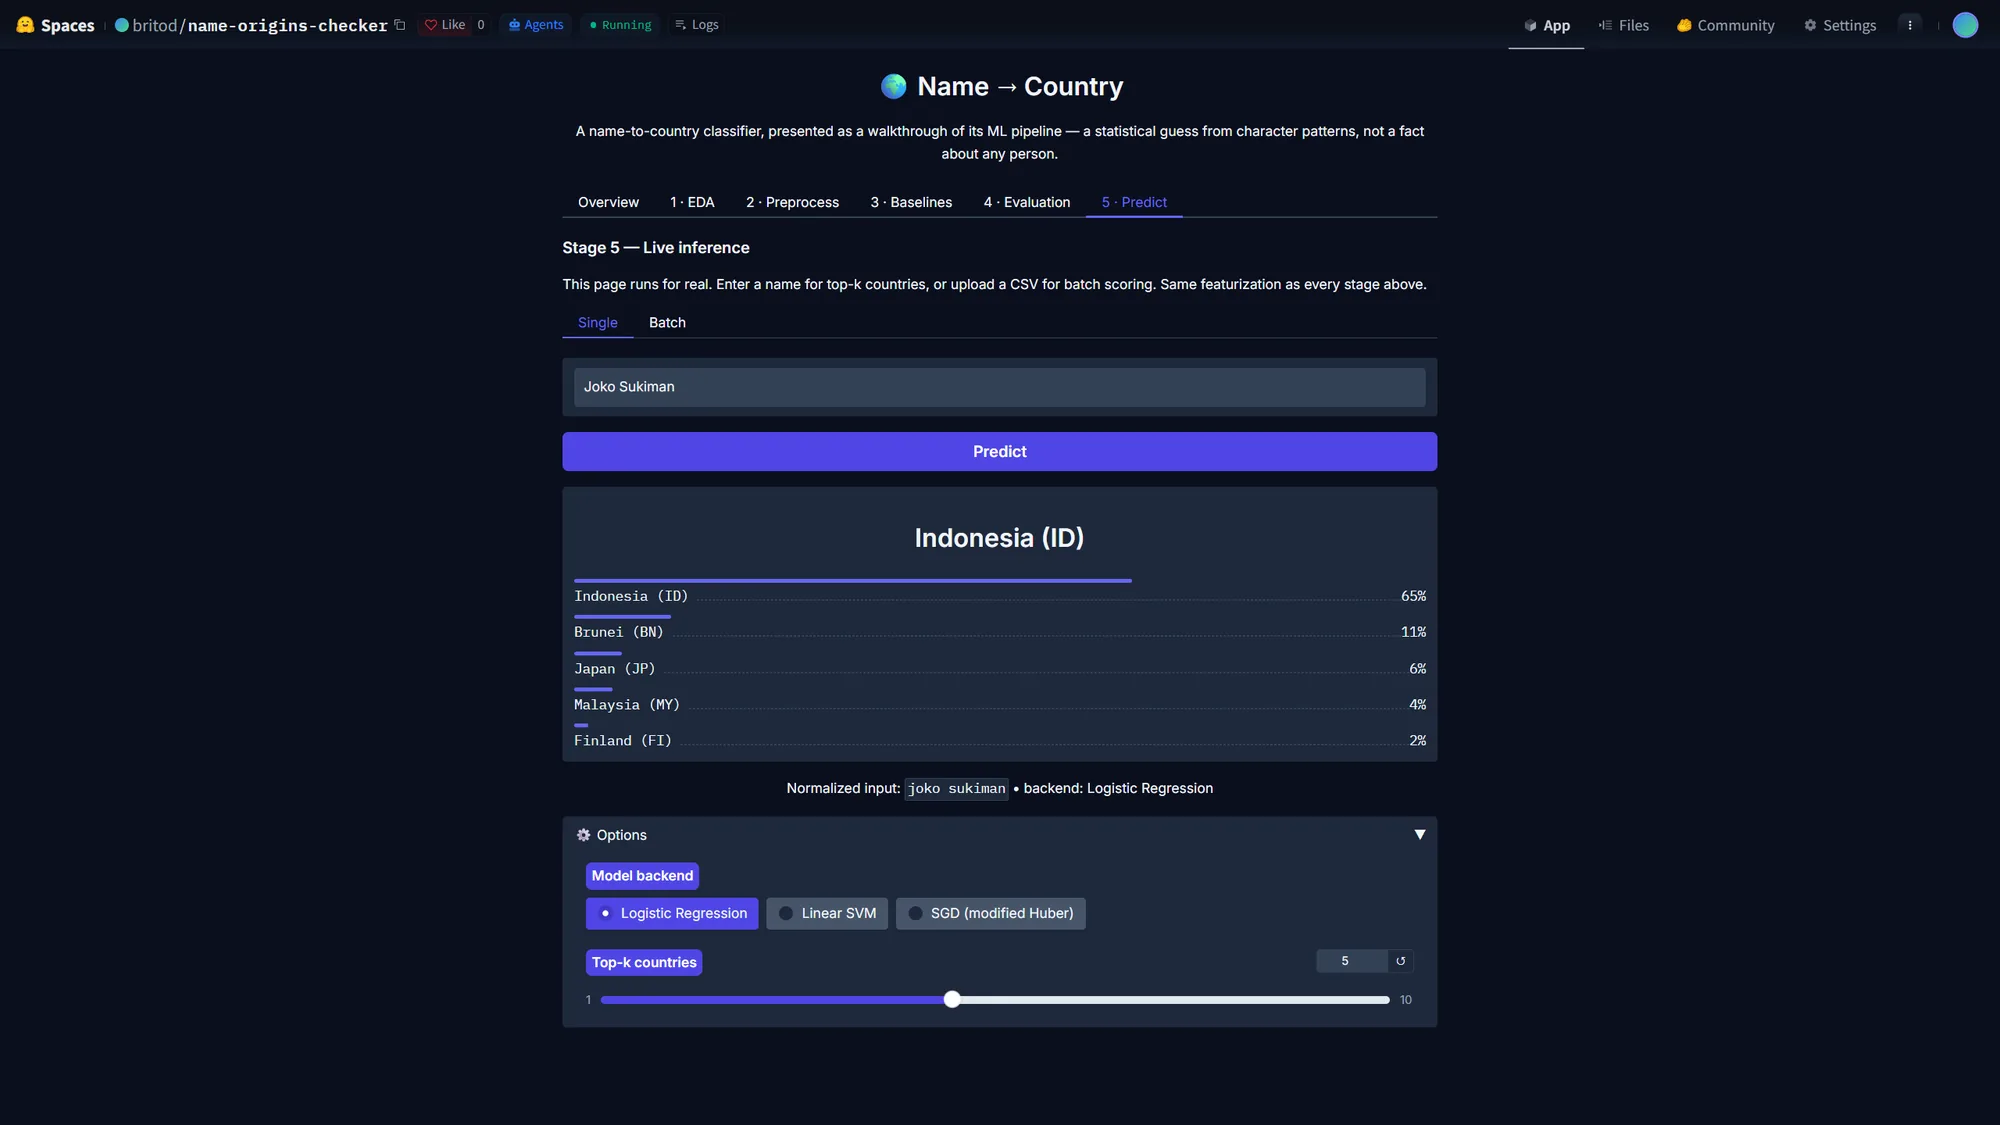
02 — Approach
Five runnable pipeline stages — EDA, preprocess, train, evaluate, predict — each invokable on its own and chained by one entry point. Preprocessing synthesises realistic full names by sampling forenames and surnames weighted by their real per-country counts, so name popularity is preserved while matching the inference contract. Names are NFD-decomposed, accent-stripped and reduced to a-z before char n-gram TF-IDF feeds three linear classifiers. Evaluation reports a set-lenient score alongside the strict one to separate real model error from irreducible name ambiguity.