01 — Problem
Indonesian social-media profanity is almost never written plainly. Users space letters out (a n j i n g), swap in digits (b4b1, k0nt0l), and lean on regional slang no formal dictionary covers, so a word-level classifier trained on clean text misses most of what it is meant to catch. Moderation queues also need priority, not a binary flag: a mild insult and a strong hate-speech post should not land in the same bucket.
02 — Approach
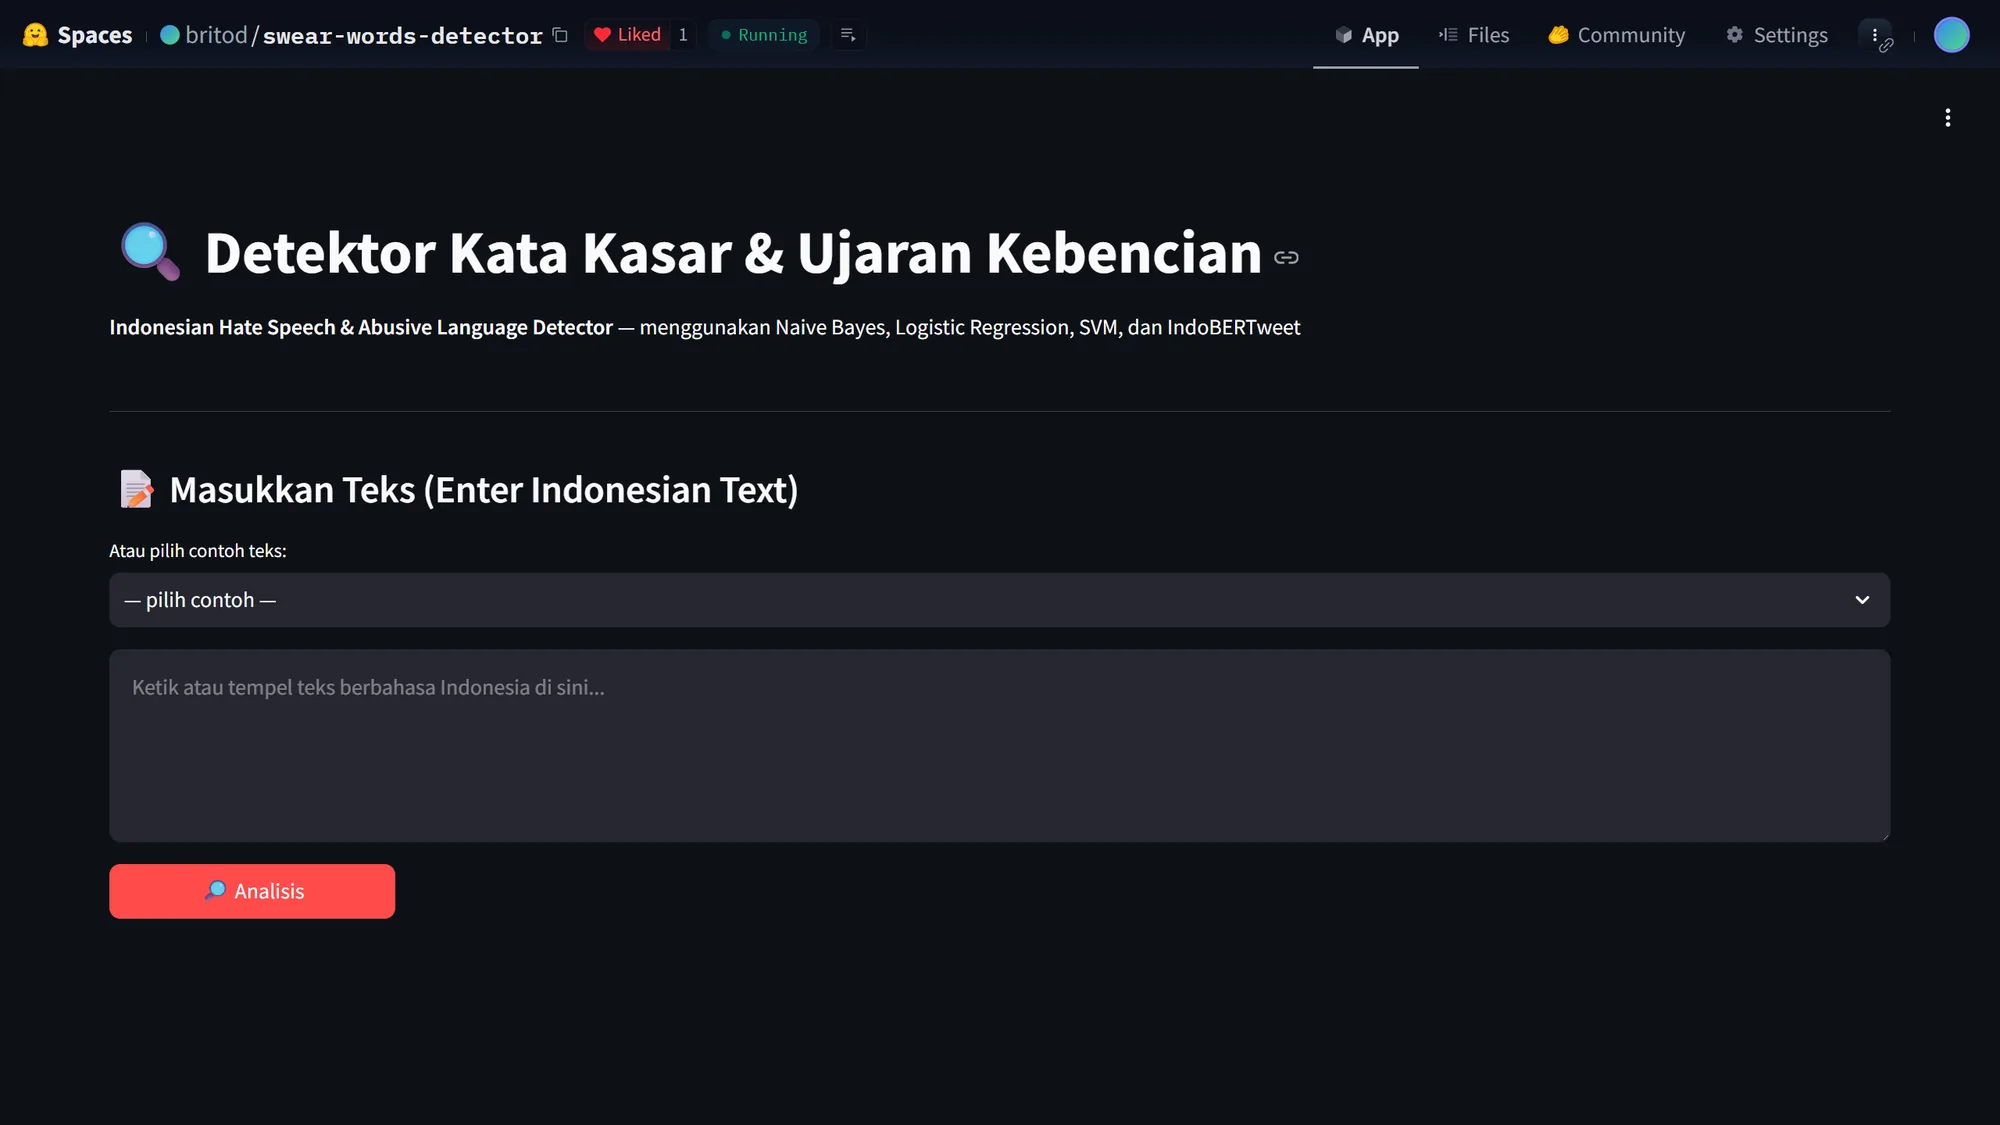
The multi-label source annotation was collapsed into a single ordinal 0-3 severity label, checking the strongest signal first so a tweet marked both abusive and strongly hateful lands at level 3. Normalisation collapses spaced-out characters and substitutes leet-speak before the text branches two ways: straight to IndoBERTweet's tokeniser, or through slang normalisation and Sastrawi stemming into a char_wb TF-IDF (2-5 grams, 50k features) feeding Naive Bayes, Logistic Regression and LinearSVC. Serving repeats both branches to keep train/serve parity.
03 — My role
AI Engineer & Deployment. Built end to end — the ordinal label mapping, both preprocessing branches, all four models and the Streamlit app. Originally an NLP Assurance of Learning assignment.
Team project
Results
On a held-out stratified test set of 1,317 tweets, char n-gram Logistic Regression reached 0.74 macro-F1 and beat the fine-tuned IndoBERTweet at 0.71. With ~13k noisy, heavily obfuscated tweets, character n-grams generalise better than a wordpiece vocabulary that has never seen b4b1. Macro-F1 is the honest headline because the classes are 12x imbalanced, so accuracy flatters a model that never predicts level 3 at all. Every model still collapses on level 2, where recall runs 0.33-0.60, because the weak/moderate boundary is annotator-subjective in the source data. The app serves all four models plus a majority vote so no single model's failure is silent.